How it works
Compare documents
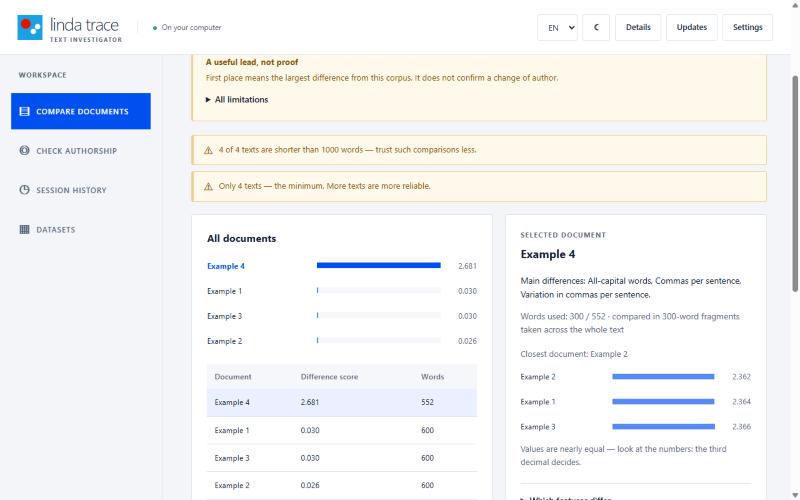
Load 4–200 documents in one language. Each should contain at least 300 words; about 1,000 is better. Linda Trace ranks documents by how much each differs in style from the rest, identifies the most different document, shows the features behind it (each value against the median of the other documents), highlights the 300-word fragments that differ most, and draws a 2D style map.
Check authorship
Load questioned texts and known-author samples: at least two samples per author and at least two authors. Linda Trace shows the nearest candidate authors by style. These are candidates, not probabilities.
Formats: TXT, DOCX, PDF, RTF, HTML and Markdown. TXT encodings UTF-8, UTF-16 and selectable Windows-1251/1250/1252. Export to HTML, PDF, JSON or a ZIP archive with file hashes. Saved datasets (cases) stay on your PC. Light, dark and high-contrast themes; interface in Russian, English and Polish.
The method combines about 250 stylometric features, character 3–4-gram vectors (a bundled resource of 2,000 features per language, trained only on documented public-domain and CC0 literary prose: 407 works), and a directional cosine-delta score into one ranking. Statistical p-values are not shown because the null model was not validated.
PrivacyAll analysis runs locally. Uploaded texts are never sent anywhere; the app only downloads update files (see Updates).